Your chapter's draft,
in 5 minutes, locally.
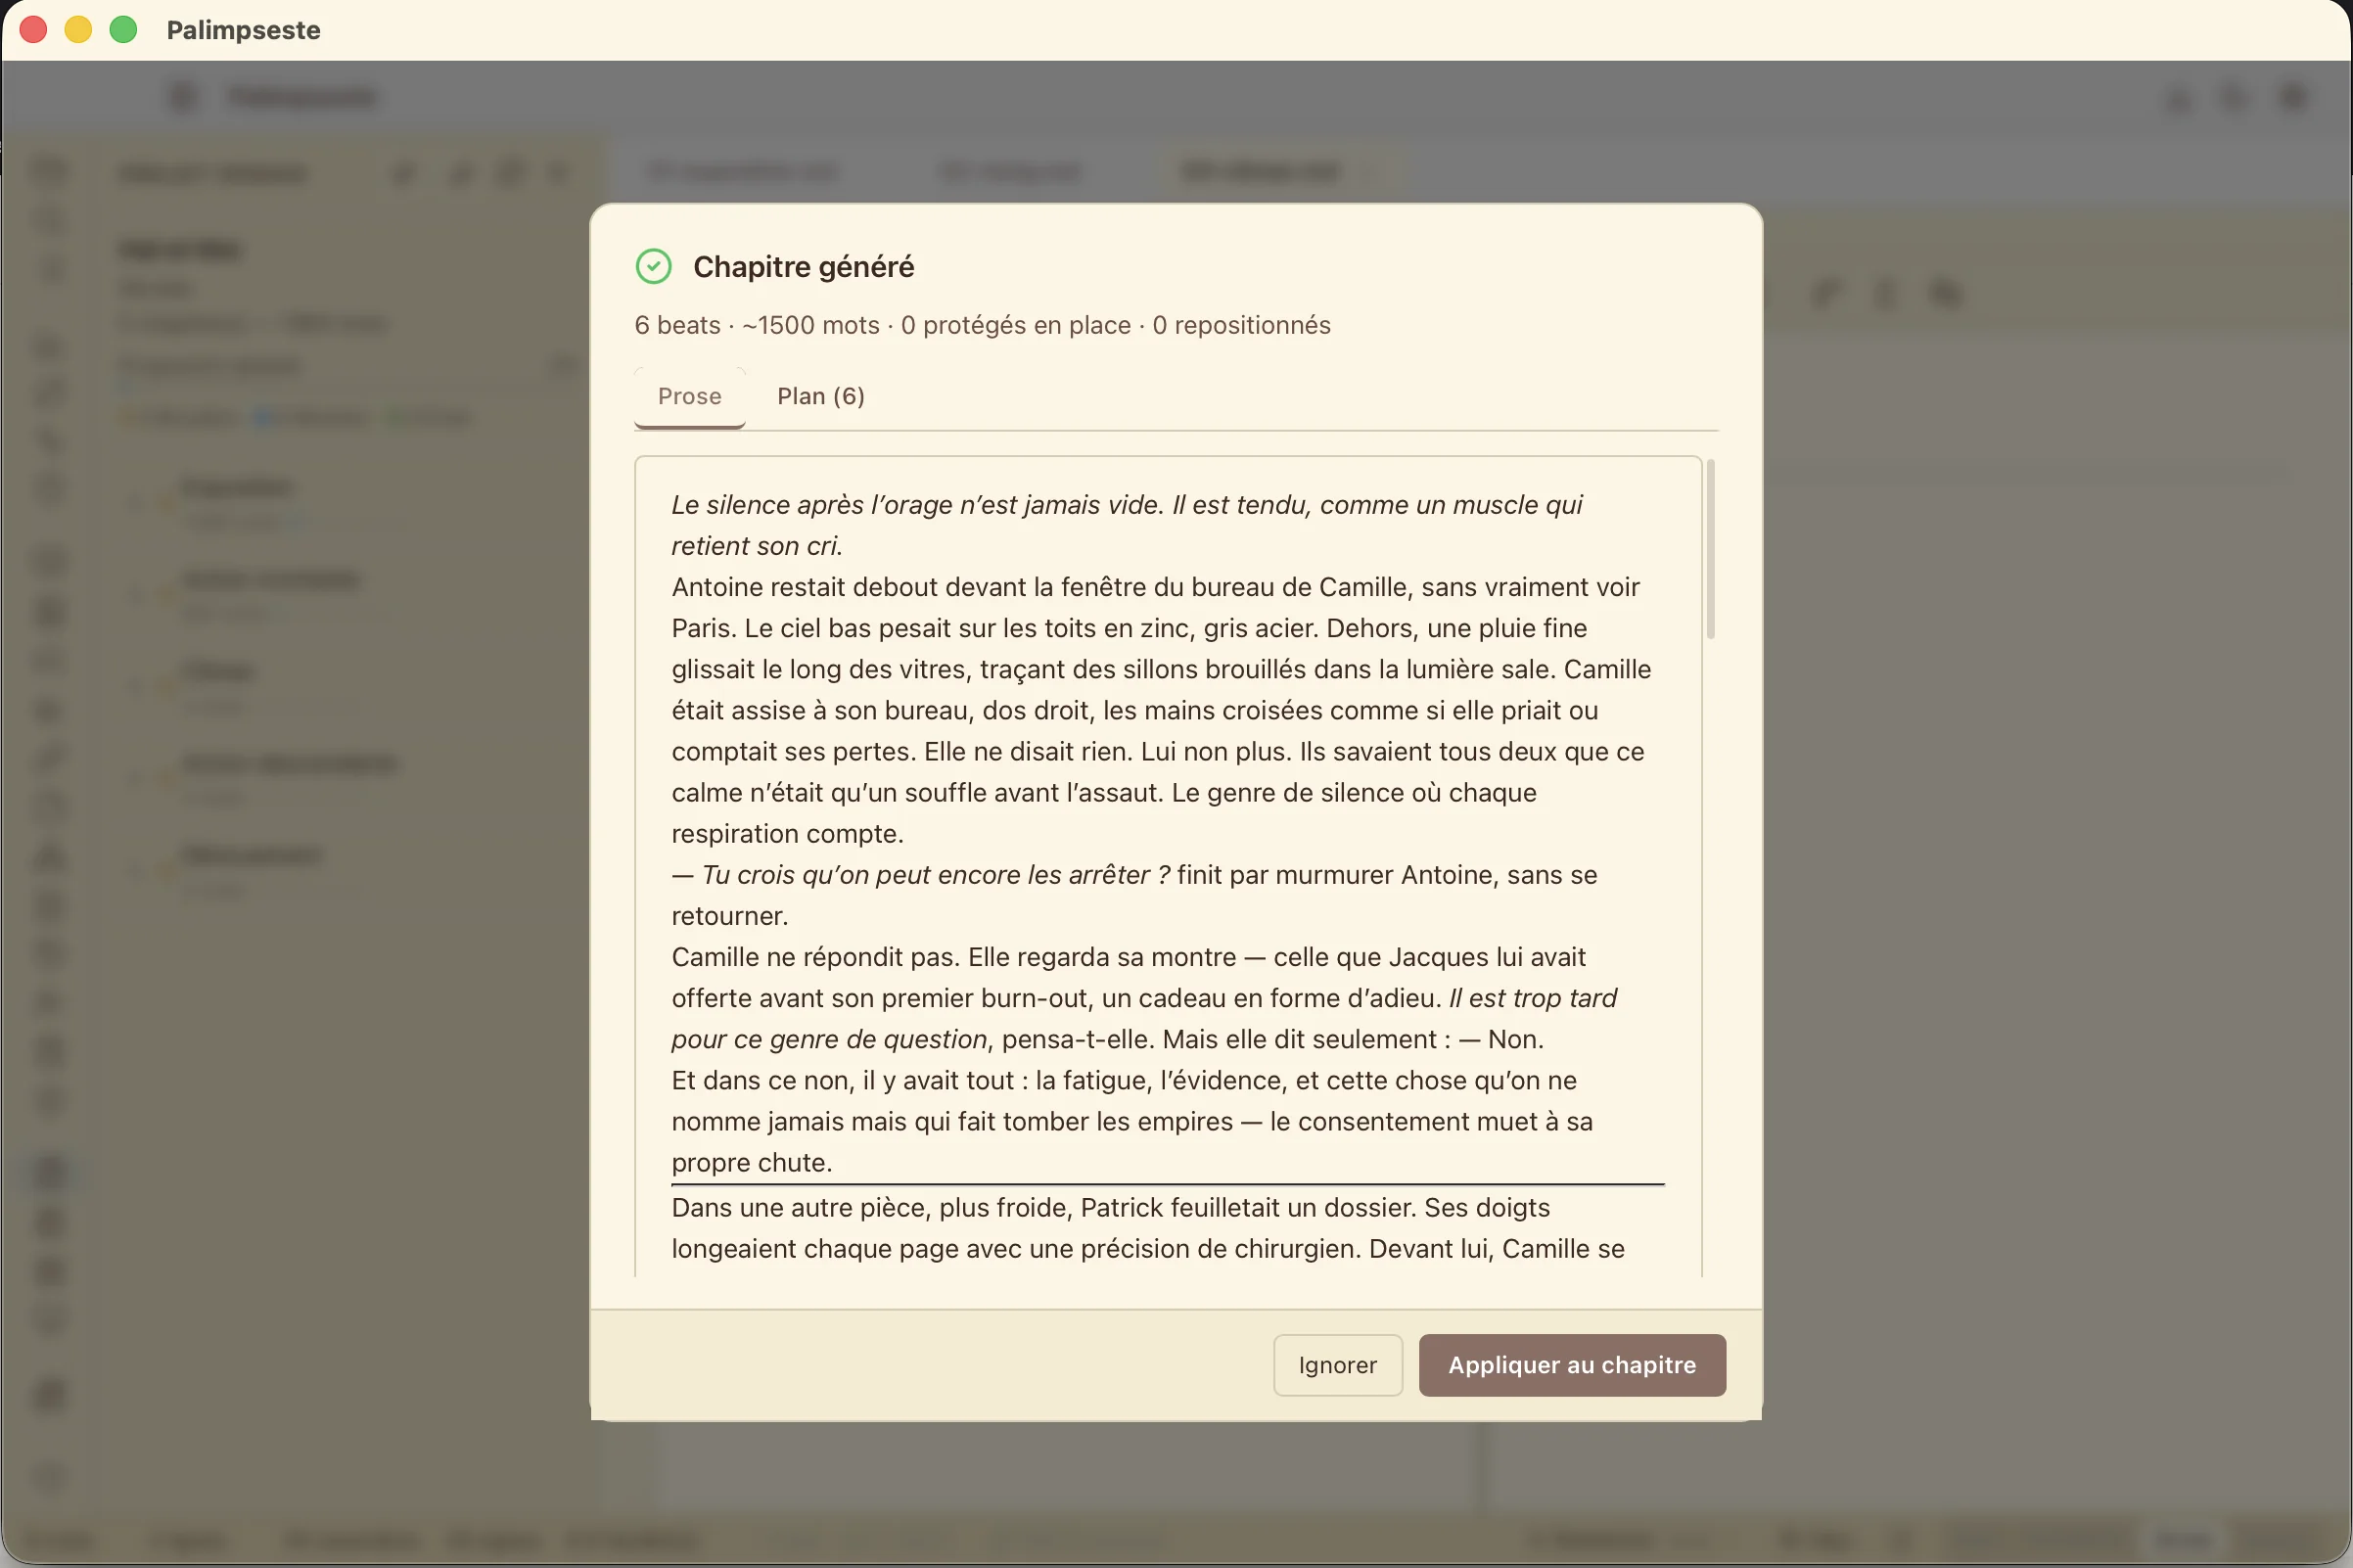
Story Engine reads your Story Bible, narrative arcs and target chapter synopsis — then writes 1500 words of prose in your project's language, in your persona's voice. Anthropic Claude, Ollama, LM Studio. Your call.
A chapter generator, built local-first
Everything you need to write a chapter, without mandatory cloud dependency or proprietary format. All included in your subscription at €59.99/year VAT incl.
- ✓ Full chapter generation — two-pass pipeline (beat-by-beat plan then markdown prose), about 1500 words per chapter.
- ✓ Fully local-capable — your manuscripts stay on your disk. With a local model (Ollama, LM Studio), no fragment leaves your machine.
- ✓ Cloud when you choose it — Anthropic Claude, OpenAI GPT, via your own API key. No middleman markup, no cross-subscription.
- ✓ Native UI in 5 languages — French, English, German, Spanish, Italian. Generation language follows the project's.
- ✓ Story Bible + Plot Threads + Synopses integrated — the AI reads your character cards, narrative arcs, and chapter synopsis before writing.
- ✓ Three work profiles — novelist, researcher, journalist. Each tunes vocabulary and narrative structure.
- ✓ Open formats only — Markdown, YAML, JSON. Git-versionable. Readable in ten years, in any editor.
A two-pass pipeline — no random prose
Story Engine doesn't just "generate text." It plans first the chapter's structure (who speaks, where, why, how many words), then writes the prose following the plan. You validate the plan before writing, and see both at apply time.

<!-- locked --> blocks, full restarts from scratch), check the LLM and output budget.
Beat-by-beat plan

3-8 beats per chapter — each with its role (opening, climax, resolution…), participants, location, dramatic intent, and word budget. Structured JSON, schema-validated.
Markdown prose

~1500 words of prose in a single call — not beat-by-beat, to keep internal coherence between scenes. Persona's style guide prepended to the prompt, glossary vocabulary honored.
Atomic preservation

Passages wrapped in <!-- locked --> ... <!-- /locked --> survive verbatim. Section ID anchors (<!-- id: sec-XXX -->) are auto-protected too. .bak backup before any write, hot-swap of the open buffer.
Three professional profiles — same engine, tailored vocabulary
📖 Novelist
Beats: opening · rising · midpoint · climax · resolution · transition
Narrative prose, lively dialogue, sensoriality. Show don't tell. Short sentences for tension, longer ones for reflection.
🎓 Researcher
Beats: premise · evidence · counter-argument · synthesis · implication
Argumentative prose. Explicit logical connectors ("therefore", "however"). Citations from provided sources. One claim per paragraph.
📰 Journalist
Beats: lede · context · development · interview-quote · conclusion
Journalistic prose. Lead with the news, not the back-story. Active voice. Systematic attribution ("according to X"). Short paragraphs.
For those who want the details
Supported models
- Anthropic Claude Sonnet 4.6+, Opus, Haiku
- OpenAI GPT-4.1, GPT-4o, o3, o4
- Ollama Qwen 2.5 32B (recommandé), Gemma 3 27B, Llama 3.3 70B, Mistral Small 3, Phi-4 14B
- LM Studio tout modèle compatible OpenAI API
Resilient chain (Sprint H)
When a local model refuses to emit valid JSON (panic chain-of-thought, markdown fences, MoE channels), Palimpseste auto-chains 4 strategies:
native → cooldown → stripped → cloud fallback (implicit opt-in).
Context budget
Pre-flight dialog showing input + estimated output vs the model's window. Red "Budget tight" banner when usage exceeds 70% of the context. Persona docs and bible filtered by target chapter to stay under budget.
Cross-chapter continuity
Previous and next chapters' synopses (200-char cap each) are injected into the prompt — the AI avoids retelling and can foreshadow what's next, without blowing the token budget.

Ready to try?
Download Palimpseste free. Story Engine is included in the Pro plan (from €6.99/month VAT incl.).